- powerful postraining method for transferring the specialist RL teacher model performance to a student without causing Mode/Entropy Collapse, less “jagged”
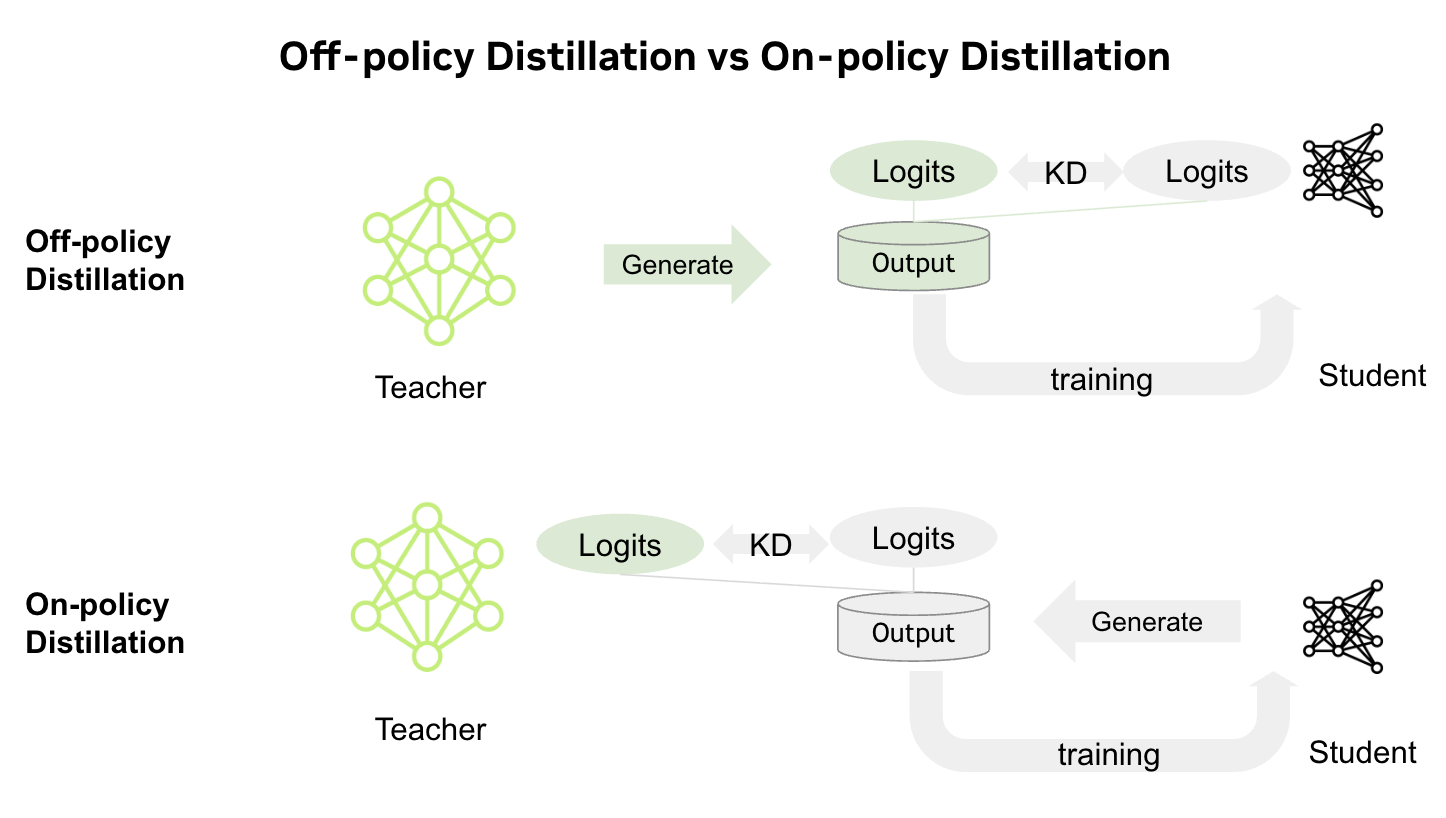
- instead of Off Policy Distillation where a student model ( usually smaller one, old purpose of distillation ) instead measures divergence for the whole logit spectrum per token, the student model in OPD just generates its own reponses/Tokens which then get graded by the teacher.
- classic case where one can see the divergence would be a student learning from a teacher math expert, where say the student model makes a small error early on in the distillation run, this is retained and now worsened by the fact that the student is conditioning its following output on this error; of policy learning is just learning distribution approximation and not efficient error correctoin
- good example was phrased to me through learning Chess from a grandmaster ( the teacher model )
- Off policy learning would be watching the grandmaster play, it is informative and you learn what looks like really good behavior, but you are lost on how to apply that
- On policy is having the grandmaster watch YOU play, you making a move and the grandmaster talking each move over wtih you about consequences/plans from that move. Much more efficient, directly building off of how YOU improve your performance and not just what good performance looks like
- Mode Seeking Alignment: think of think of this as reverse KL Divergence, by minimizing KL on students own rollouts, it isnt forced to mimic reasoning patterns that it itself is not capable of achieving. this instead opts to reinforce preexisting paths already within its own distribution that the teacher also approves of, preventing destructive weight updates.
- On Policy Self Distillation rsi continual learning asi agi method confirmed!?!?
reverse kl objective: