10-13-2026 update of note: while I have this note specifically for mech interp, I use the note more generally for general interp methods, especially since a lot of my work goes beyond LLMs and more with Self Supervised Learning and Representation models
important a subfield of AI interpretability that focuses on understanding the internal workings of AI models, particularly large language models (LLMs). It aims to uncover how these models process information and make decisions, often through techniques like circuit analysis, feature visualization, and probing.
- 10-15-2026 cool new breakthrough from one of the authors of the OG Polysemanticity paper: Neural Networks Are Already Clean
Common Techniques
Anthropic and many other organizations have been working on mechanistic interpretability using techniques that focus on a single neuron or a small group of neurons.
What this looks like in practice looking at the probability distribution for a sample query, say “The reliability of wikipedia is very…”, finding something interesting like a probability for “questionable” being high, and then going through layer by layer unembedding the logits to see which neurons are contributing to that probability.
When you have found a neuron of interest, you could try a few things to investigate, something like modifying the neuron value to see how it affects the output, or plotting a heatmap over the token sequence to see what parts of the input are activating the neuron.
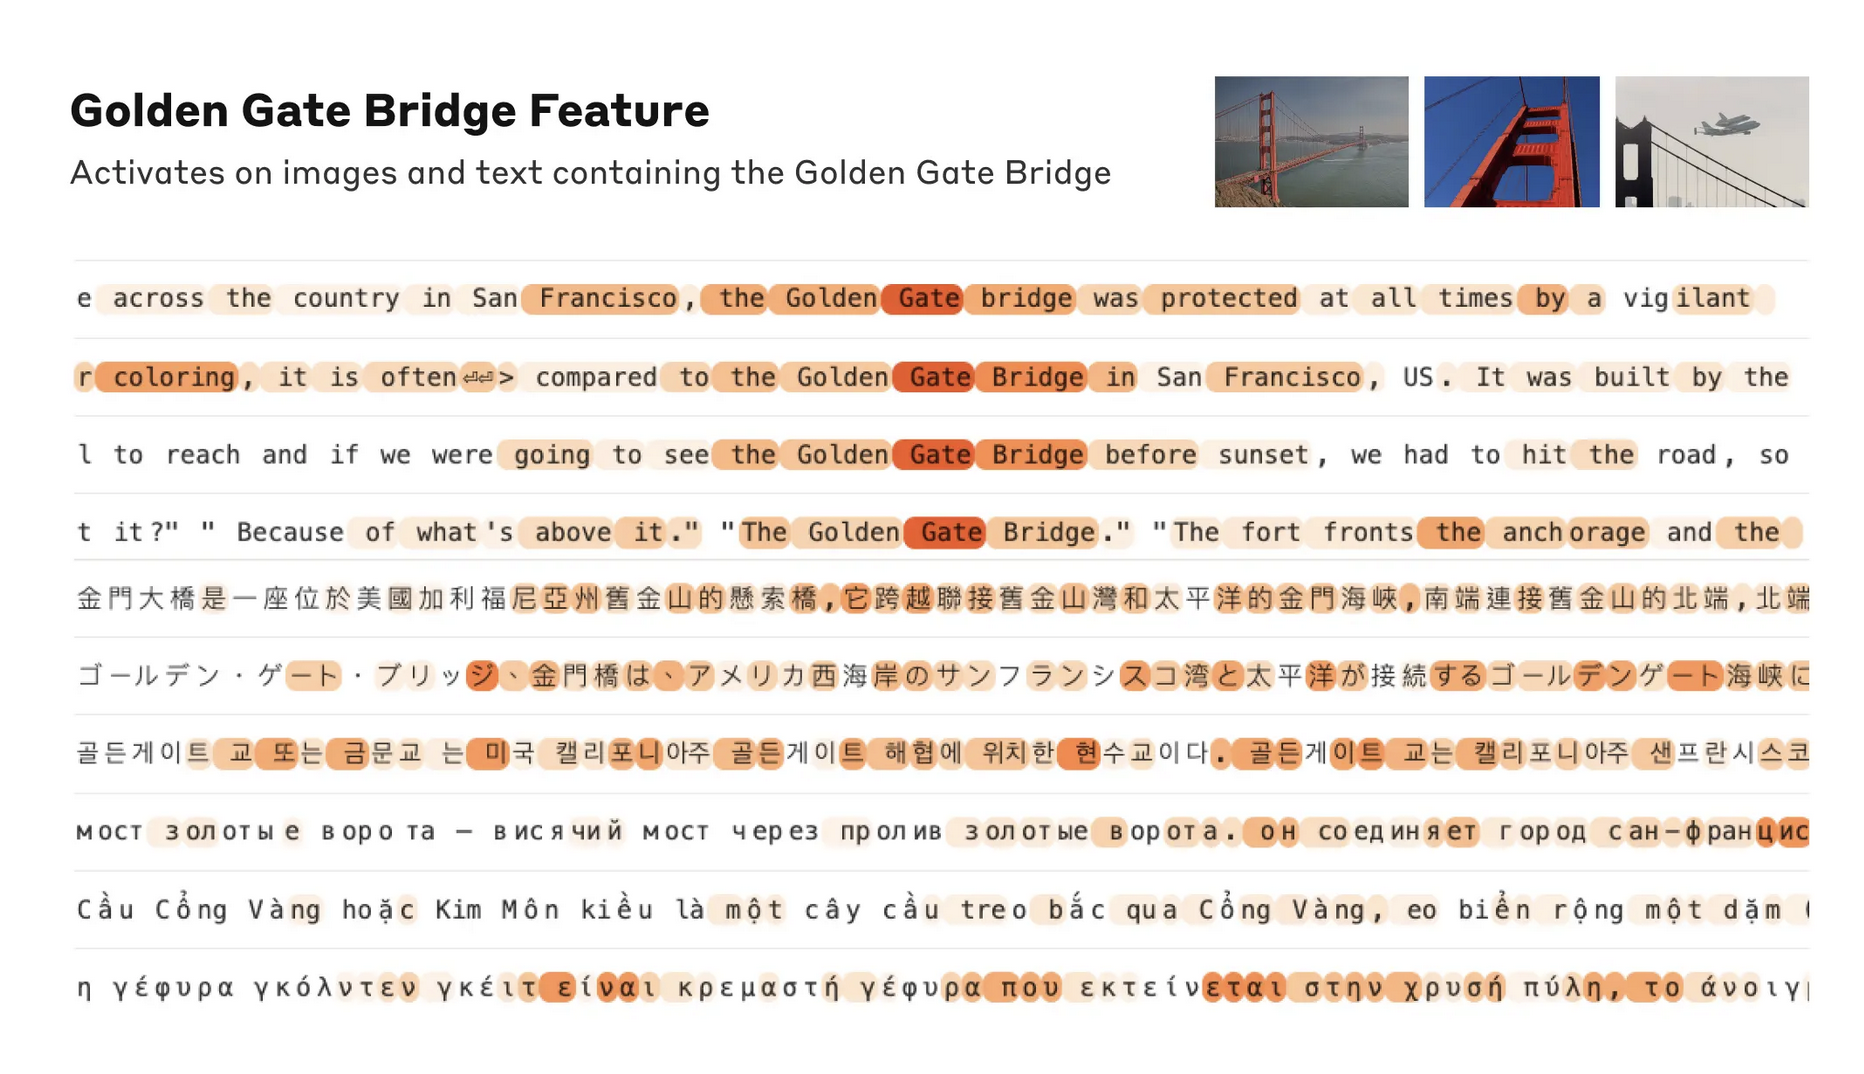
Anthropic: A feature sensitive to mentions of the Golden Gate Bridge fires on a range of model inputs, from English mentions of the name of the bridge to discussions in Japanese, Chinese, Greek, Vietnamese, Russian, and an image. The orange color denotes the words or word-parts on which the feature is active.
Some classic methods for Large Language Model interp:
- Sparse Autoencoders: A promising approach that uses a separate learning algorithm to extract model features that often align with human-understandable concepts. Researchers can then amplify or suppress these features to observe their effect on the model’s behavior.
- Direct Modification of Neuron Values: A straightforward method to test a neuron’s function by manually setting its output to a very high or low value. By observing the impact on the model’s predictions, one can infer what the neuron has learned.
- Searching for Maximal Activation Examples: To determine what a specific neuron or feature represents, one can search through a dataset for text examples that cause it to activate most strongly.
- Modifying Model Architecture: An experimental technique to combat polysemanticity (where one neuron represents multiple unrelated concepts) by changing the model’s architecture to encourage fewer neurons to fire for any given input. The goal is to isolate concepts to more specific neurons.
- Sparse Cross-Autoencoders: A developing approach that aims to overcome limitations of standard sparse autoencoders. It looks at multiple locations in the model simultaneously to better disentangle cross-layer superposition.
Superposition And Polysemanticity
A theory that has emerged from mechanistic interpretability research is that of superposition and polysemanticity. This theory suggests that neural networks often encode multiple unrelated concepts within the same neuron or feature, leading to complex and entangled representations.
Good Tools
- I quite enjoy Linear Probes for their use in Representation models, but also very applicable for learning where a model forms a concept. tests what infromation is accessible within a representation
- controlled counterfactual evaluation, making transformations or ablations to the input to see how the resultant representation is effected.
- activation patching and Ablation: removing/patching parts of the model to test causal importance of layers, components, or subspaces
- Centered Kernel Alignment, Representational Similarity Analysis
- Spectral + geometric analysis, good for measurement of collapse, redundancy(reminds me of Barlow Twins redundancy reduction), intrinsic dimensionality, anisotropy
Concept erasure and subspace interventions, Whether specific latent factors causally influence behavior
Gradient and input attribution, What features drive an output or internal activation
Training dynamics and data attribution, Why particular features emerge and what examples shape them
Sparse autoencoders and dictionary learning, More interpretable features than individual neuron axes
Circuit discovery, How components cooperate to implement computations
Disentanglement metrics, Separation of known generative factors
Libraries
- Captum is a good general purpose interp library for Ablation studies, input/layer contribution
- NNSight is the best for inspecting internal activations, modifying them during forward passes, and running controlled interventions.
- TransformerLens is the classic for language models
- pyvene is specifically for causal representation interventions, in that it is good for activation swaps, subspace interventions, causal abstraction experiments, and learned interventions.
- SAELens for Sparse Autoencoders